 |
Zehua Pei |
Biography
I am a final-year Ph.D. candidate in the Department of Computer Science and Engineering at The Chinese University of Hong Kong, supervised by Prof. Bei Yu and co-supervised by Prof. Sinno Jialin Pan. My research focuses on large language models, especially LLM agents and agentic post-training, long-context fine-tuning, efficient LLM adaptation, and model compression. My recent work studies how to improve LLM capability, efficiency, and reliability across agentic systems, code generation, and resource-constrained deployment.
I received my B.S. degree in Mathematics from The Chinese University of Hong Kong in 2022. I previously completed a research internship at Huawei Noah's Ark Lab / Foundation Model Department, where I worked on long-context LLM fine-tuning, LLM agents, and efficient MoE deployment.
At TokenRhythm, I led the agentic post-training of NeoHorse-1, an open-weight 4B/9B model family for agent workflows. I also developed NeoHorse-Jev-4B, a prefill-only model that returns structured decisions and probabilities for application-defined questions.
I will be in San Francisco for COLM 2026 this October and am currently looking for job opportunities.
I welcome discussions and collaborations with researchers and practitioners interested in LLM agents, long-context learning, efficient LLMs, and AI for code.
Recent News
Oct/2026: New blog post: Where Jev Fits in an Agent Loop, reflecting on decision models and our NeoHorse-Jev experiments.
Sep/2026: We released NeoHorse-Jev-4B, an open-weight structured decision model for agent workflows.
Sep/2026: We released NeoHorse-1 in 4B and 9B sizes. The technical report describes our routing-guided agentic post-training framework.
Sep/2026: MemDLM is accepted by NeurIPS 2026.
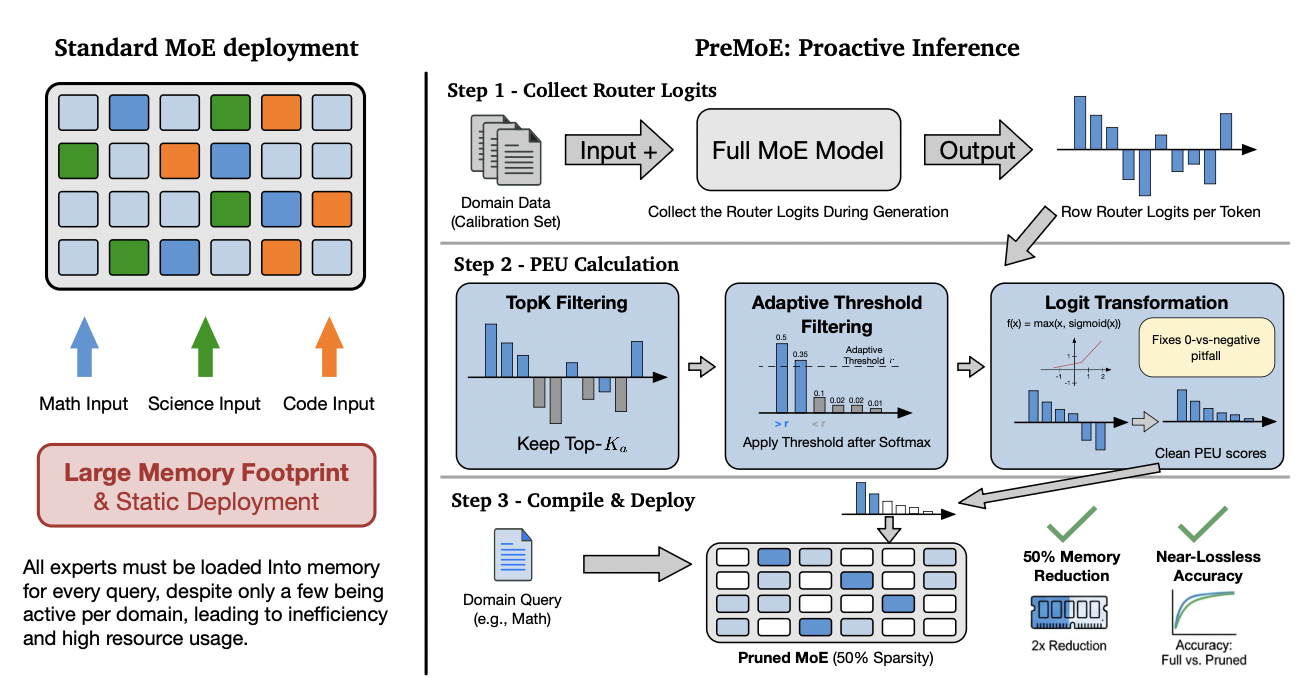
Jul/2026: PreMoE is accepted by COLM 2026.
May/2026: FocuSFT is available on arXiv, studying training-time attention dilution in long-context SFT.
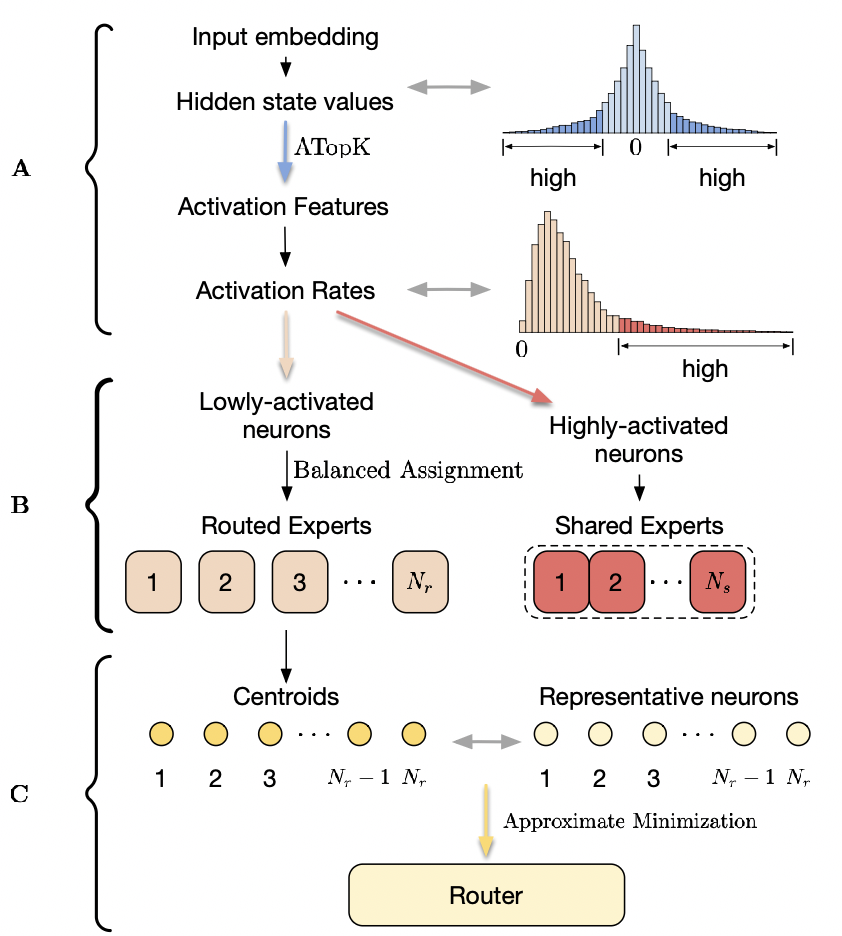
Apr/2026: Our work on analytical FFN-to-MoE restructuring is accepted by ACL 2026 Main.
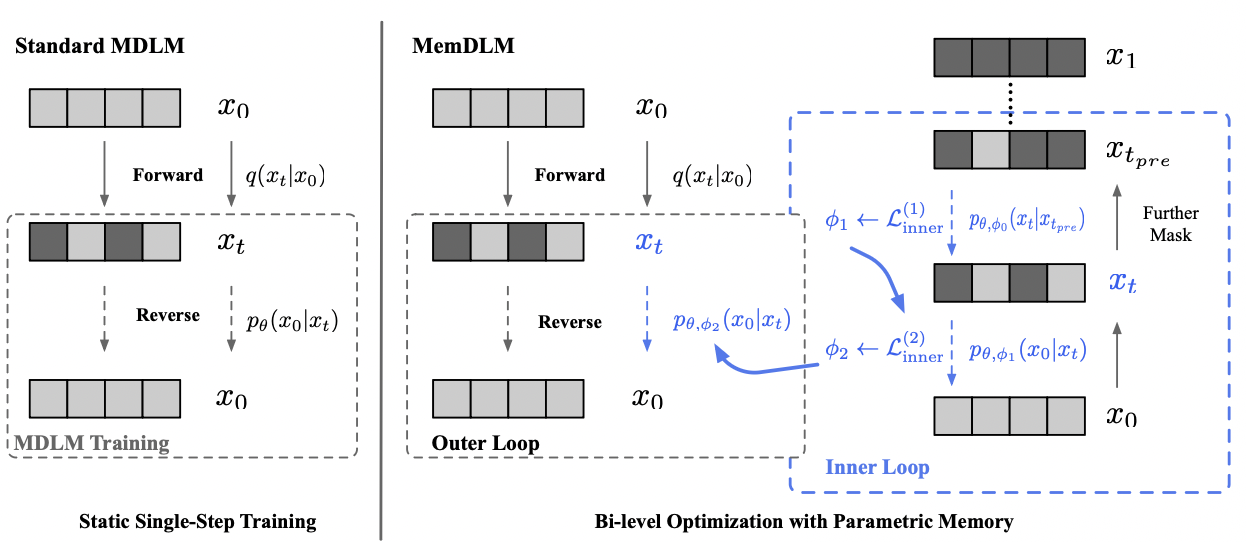
Mar/2026: MemDLM is available on arXiv, exploring parametric memory for diffusion language model training.
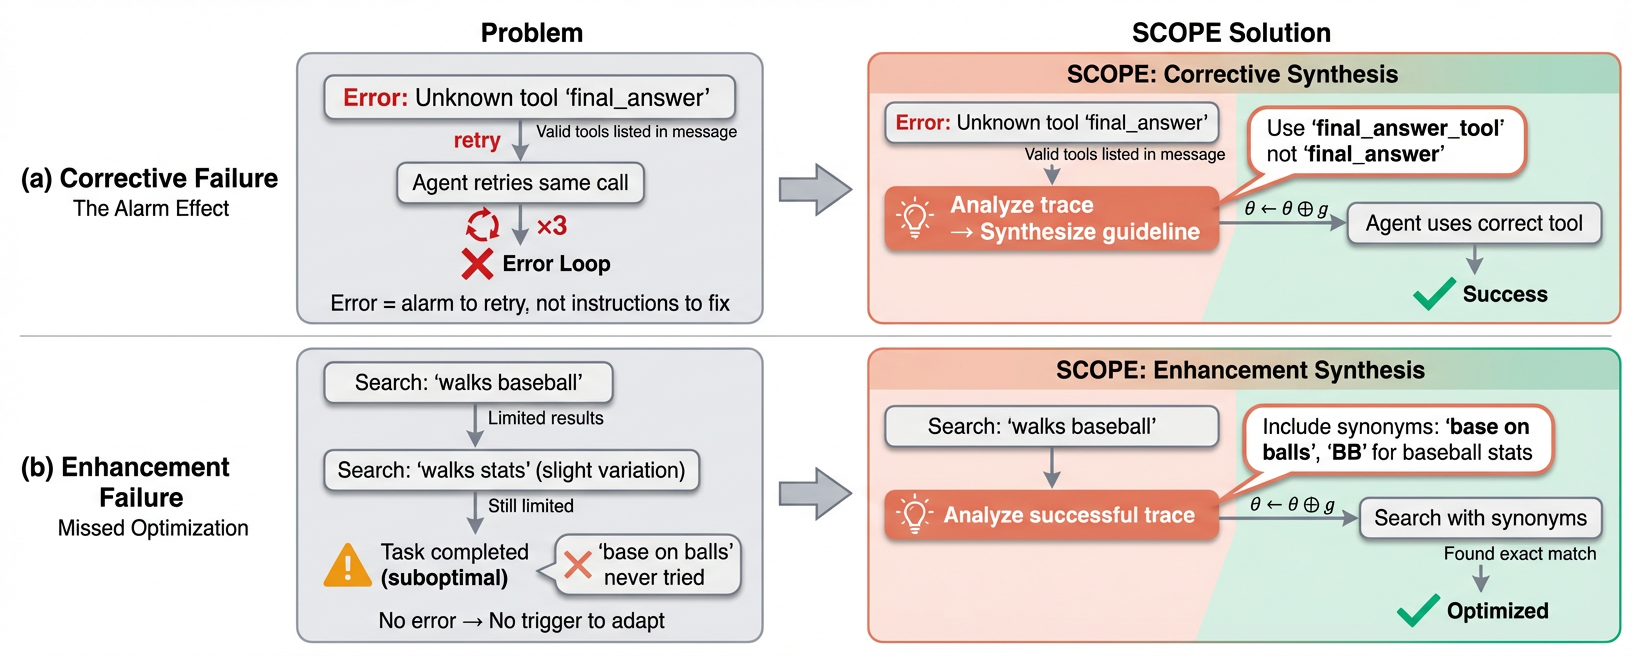
Dec/2025: SCOPE is available on arXiv, introducing prompt evolution for LLM agents.
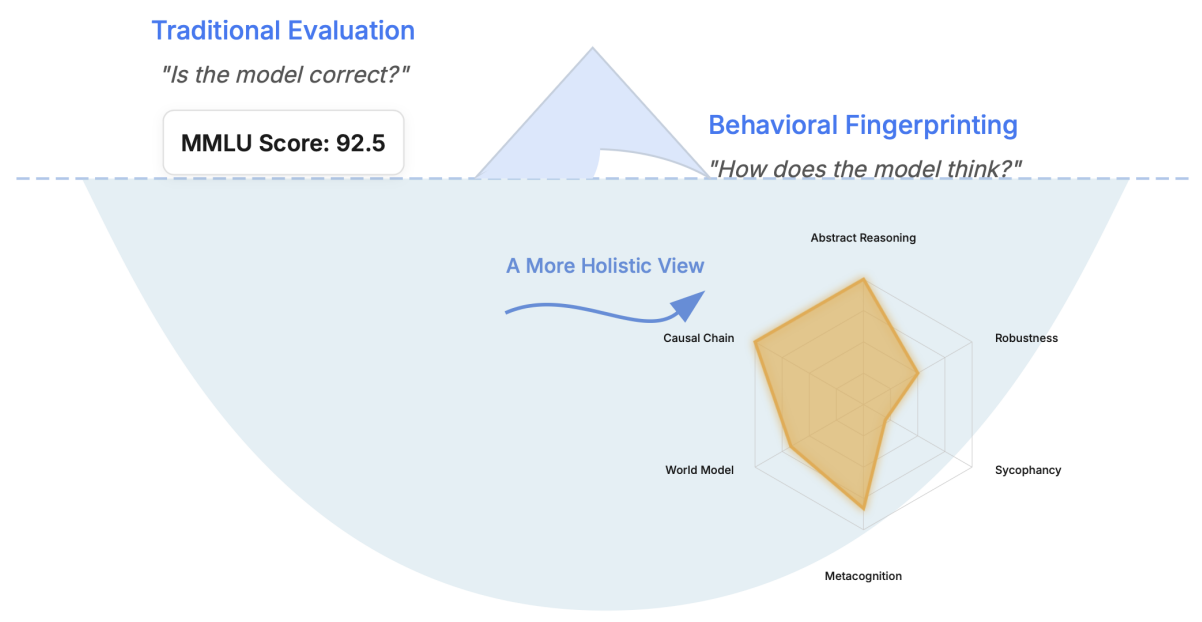
Oct/2025: Our work on behavioral fingerprinting of LLMs is accepted by Agents4Science 2025.
May/2024: BetterV is accepted by ICML 2024.
Research Interests
My research interests include:
LLM Agents: agentic post-training, structured decision models, prompt evolution, context management, agent reliability.
Long-Context LLMs: long-context fine-tuning, attention dilution, parametric memory.
Efficient LLMs: MoE restructuring, expert pruning, structured pruning, model compression.
AI for Code and EDA: controllable code generation and optimization-aware generation.
Selected Research Directions
LLMs, Agents, and Long-Context Learning
Modern LLM systems are increasingly agentic and context-heavy. My work in this direction studies how models and agents can learn to use context, rather than merely receive longer inputs.
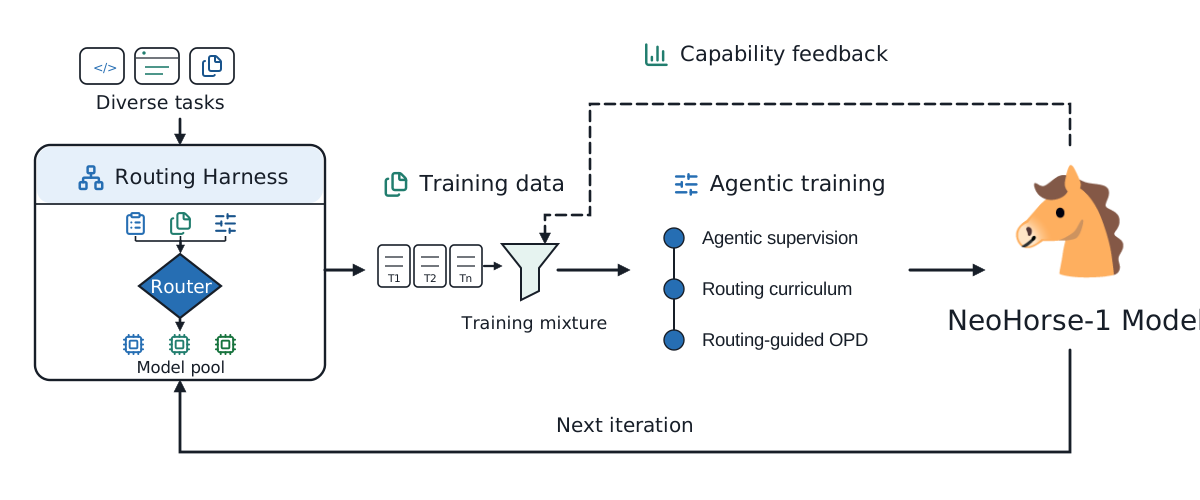
NeoHorse: Open Models for Agent Workflows. 2026. (Technical Report) (GitHub) (Models)
NeoHorse-1 provides 4B and 9B language models for tool use, coding, and instruction following. NeoHorse-Jev-4B extends the family with prefill-only structured decisions for routing, tool selection, and workflow control.
Keywords: agentic post-training; routing-guided learning; structured decisions.
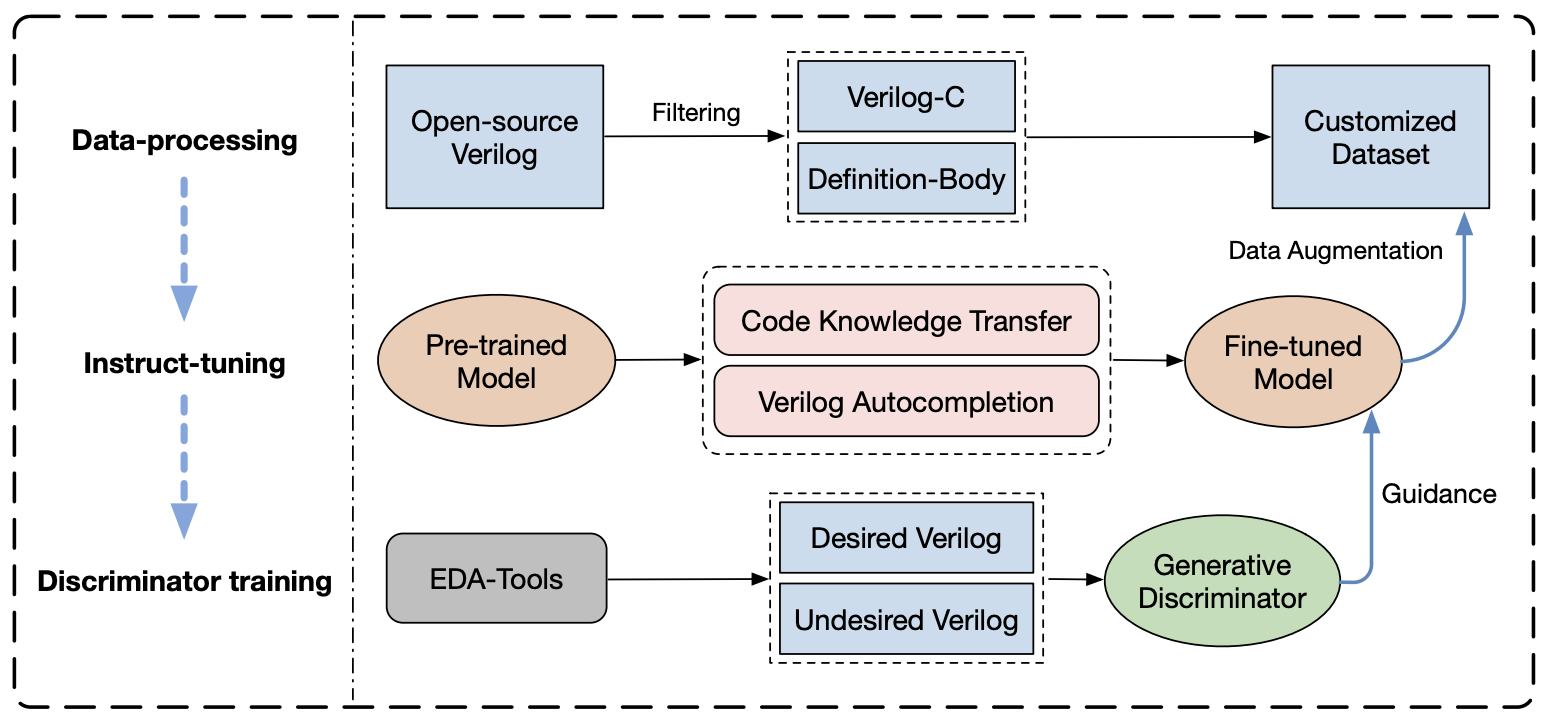
BetterV: Controlled Verilog Generation with Discriminative Guidance. ICML 2024. (Paper)
Builds a controlled Verilog-generation framework that fine-tunes LLMs on cleaned HDL data and uses task-specific generative discriminators to steer outputs toward correctness and downstream EDA objectives.
Keywords: Verilog LLMs; discriminator-guided generation; EDA optimization.
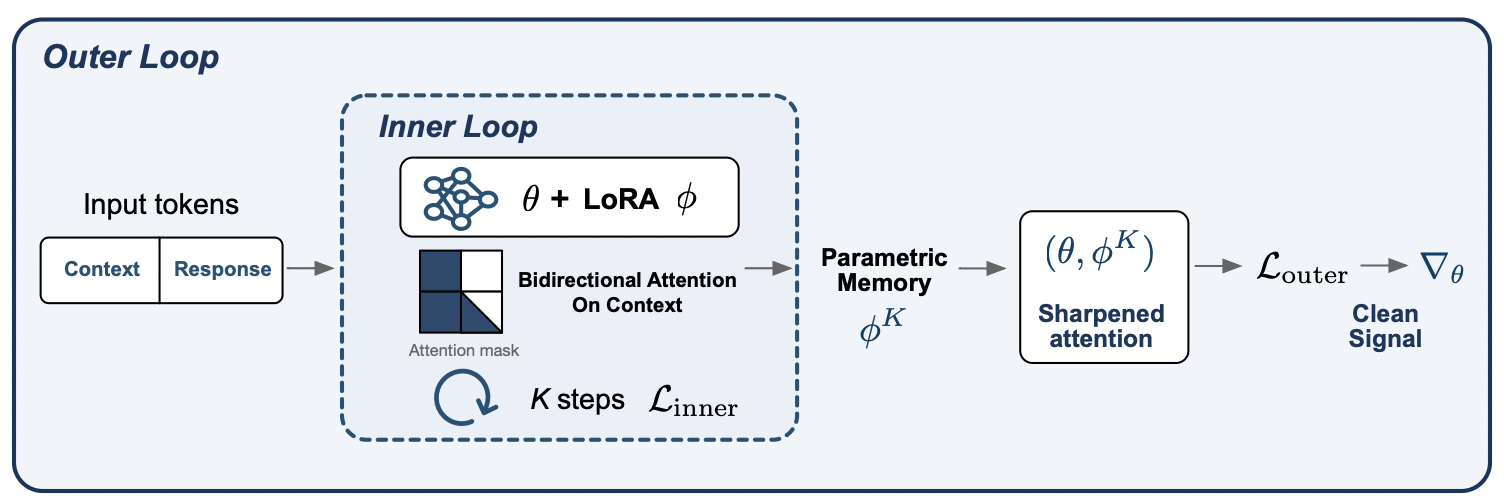
FocuSFT: Bilevel Optimization for Dilution-Aware Long-Context Fine-Tuning. arXiv preprint, 2026. (Paper) (Code)
Identifies training-time attention dilution as an overlooked bottleneck in long-context SFT and introduces bilevel parametric memory to sharpen context utilization.
Keywords: long-context fine-tuning; attention dilution; parametric memory.
Efficient LLMs and Model Compression
Efficient LLM deployment requires more than making models smaller. My work explores how to preserve or reorganize model capacity through sparsity, expert routing, and knowledge redistribution.
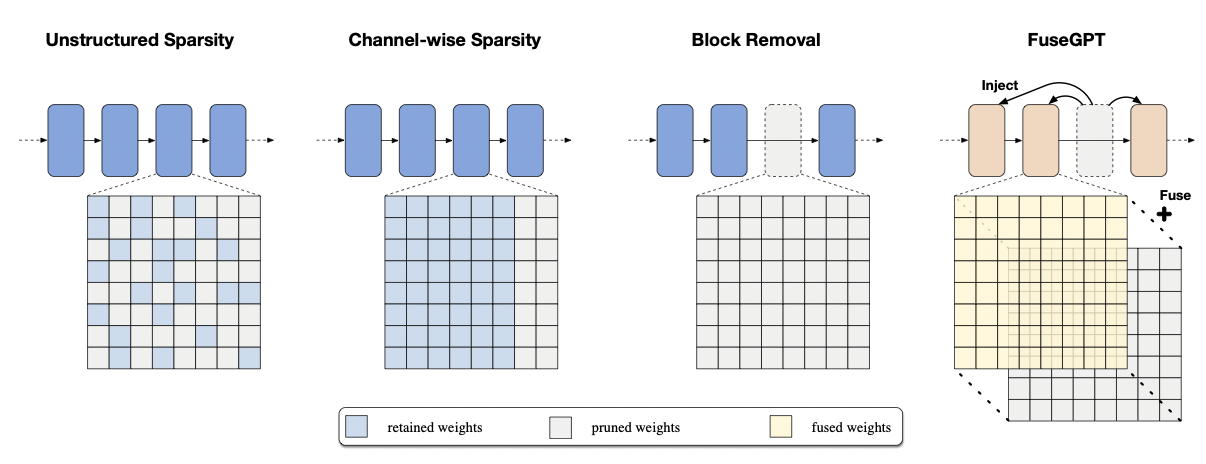
From Pruning to Grafting: Dynamic Knowledge Redistribution via Learnable Layer Fusion. arXiv preprint, 2024. (Paper) (Code)
Reframes structured pruning as learnable knowledge grafting, recycling pruned transformer blocks instead of discarding them.
Keywords: structured pruning; layer fusion; knowledge grafting.
See the full publication list and software page for more details.